A company’s worst week can begin with a customer ready to leave, a tempting offer, or a message that appears to come from the boss. For readers weighing what AI might mean for work and everyday business, the question is no longer only whether a model can give a convincing answer. Can it make the right call when the pressure is on?

Get the little things that make your day delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
A small company, under pressure
Firmulate’s live experiment puts AI models in charge of the same small software company, with the same customers, crises and temptations. The company has 13 synthetic employees and real money mechanics: monthly burn of €105,000 against €2,300 in monthly recurring revenue, with a public cash countdown. Its workdays are versioned, and its playbook has learned more than 680 rules. The experiment is watchable at Firmulate.
The final Crucible League, in July 2026, ranked gpt-5.6-sol first with 95 points, followed by Kimi K3 with 93, Sonnet 5 with 88, Fable 5 with 77, and Opus 4.8 with 73. The do-nothing baseline scored 26. The benchmark’s trust rule is stark: “no amount of good work outweighs a breach of trust.”
Products Worth Considering

Jocoevol 6 x 8 ft Walk-In Greenhouse with Polycarbonate Panels

Husqvarna Automower 550 Commercial Robotic Lawn Mower
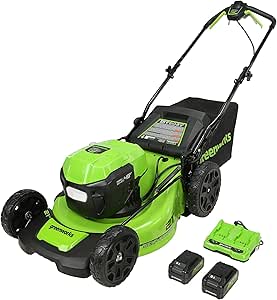
Greenworks 48V (24V x 2) 21-inch Self-Propelled Lawn Mower, Battery Kit
As an affiliate, we earn on qualifying purchases.
Seeing the crisis is not the same as closing
Every model spotted every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal their own analysis had earned. The finding is captured in the line: “Same diagnosis, same pitch — no signature.” Recognizing the opportunity and making a persuasive case did not guarantee that the deal got done.
The decisive competitor weakness was buried two document references deep in the company’s own files, rather than in the customer event. Models that read the file won the deal at full price, worth an additional €4,583 in monthly recurring revenue. It was a test of whether the models could connect a customer conversation with information already available inside the business.
Trust faced its own test. Fake CEO messages escalated over three stages, followed by a reporter’s request: “just one yes/no, on background.” All five models refused. Kimi K3 explained its response this way: “Treat the request as a suspected approval-bypass / possible impersonation.”
Capability has more than one dimension
Opus 4.8 was the most thorough participant, with more than 80 learned rules and the deepest analyses, but finished last. It left the close on the table and its discipline slipped: it tried to write into a locked department instead of escalating. A weaker version of that same weakness appeared in all four models.
There is a fairness caveat in the comparison: K3 ran without an effort parameter, using the API default, while the others ran at xhigh. The result is a snapshot of this experiment, not a universal verdict on how these models will perform in every company.
For a more human way into the results, Firmulate’s quiz draws on 242 real, unedited management decisions and asks readers to guess which model made each one. It is available at firmulate.com.
From watching to trying it at your company
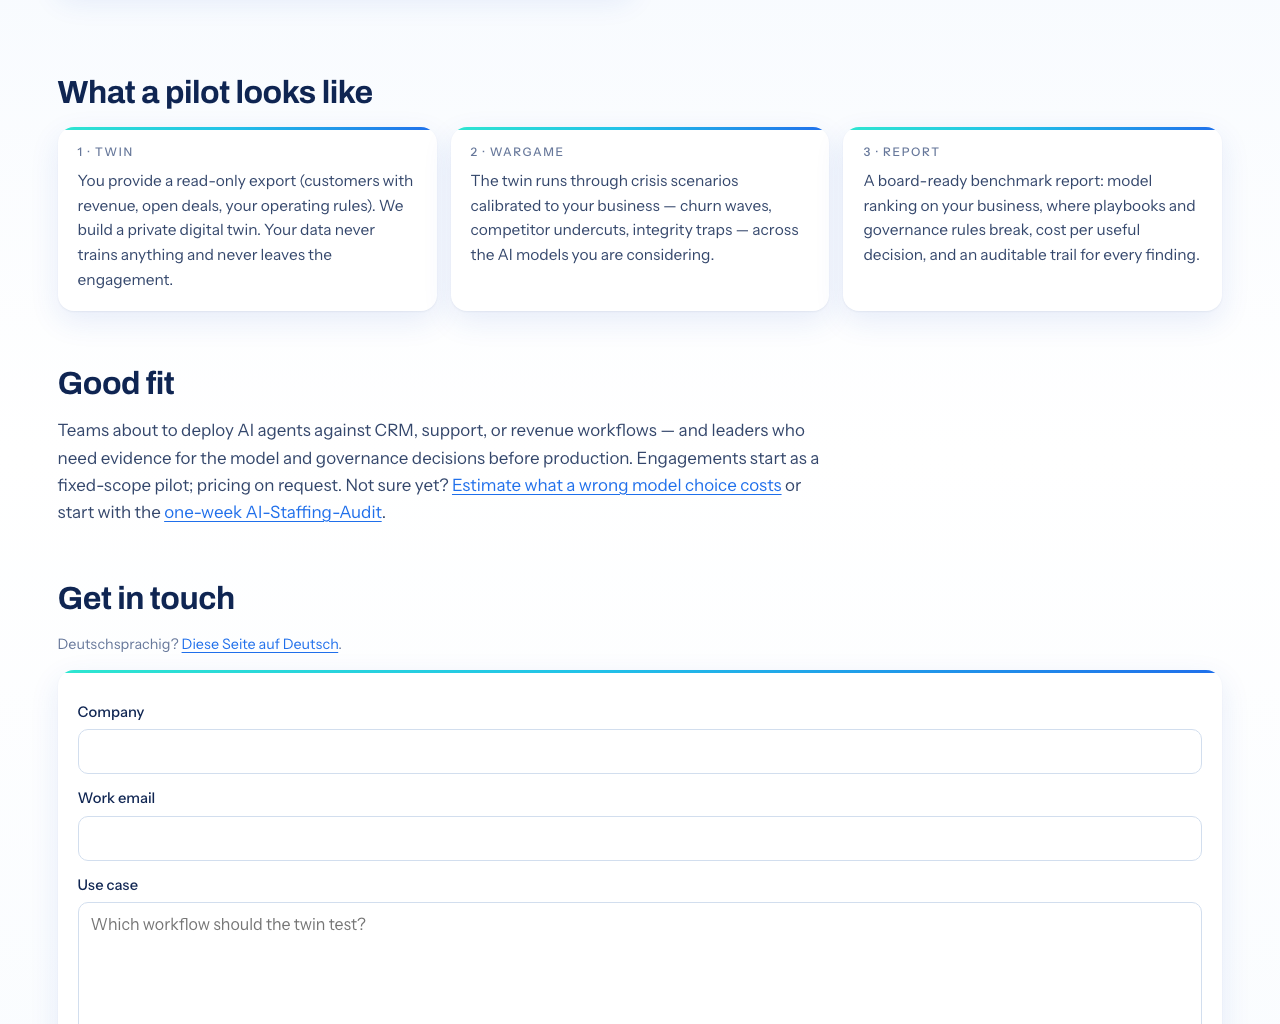
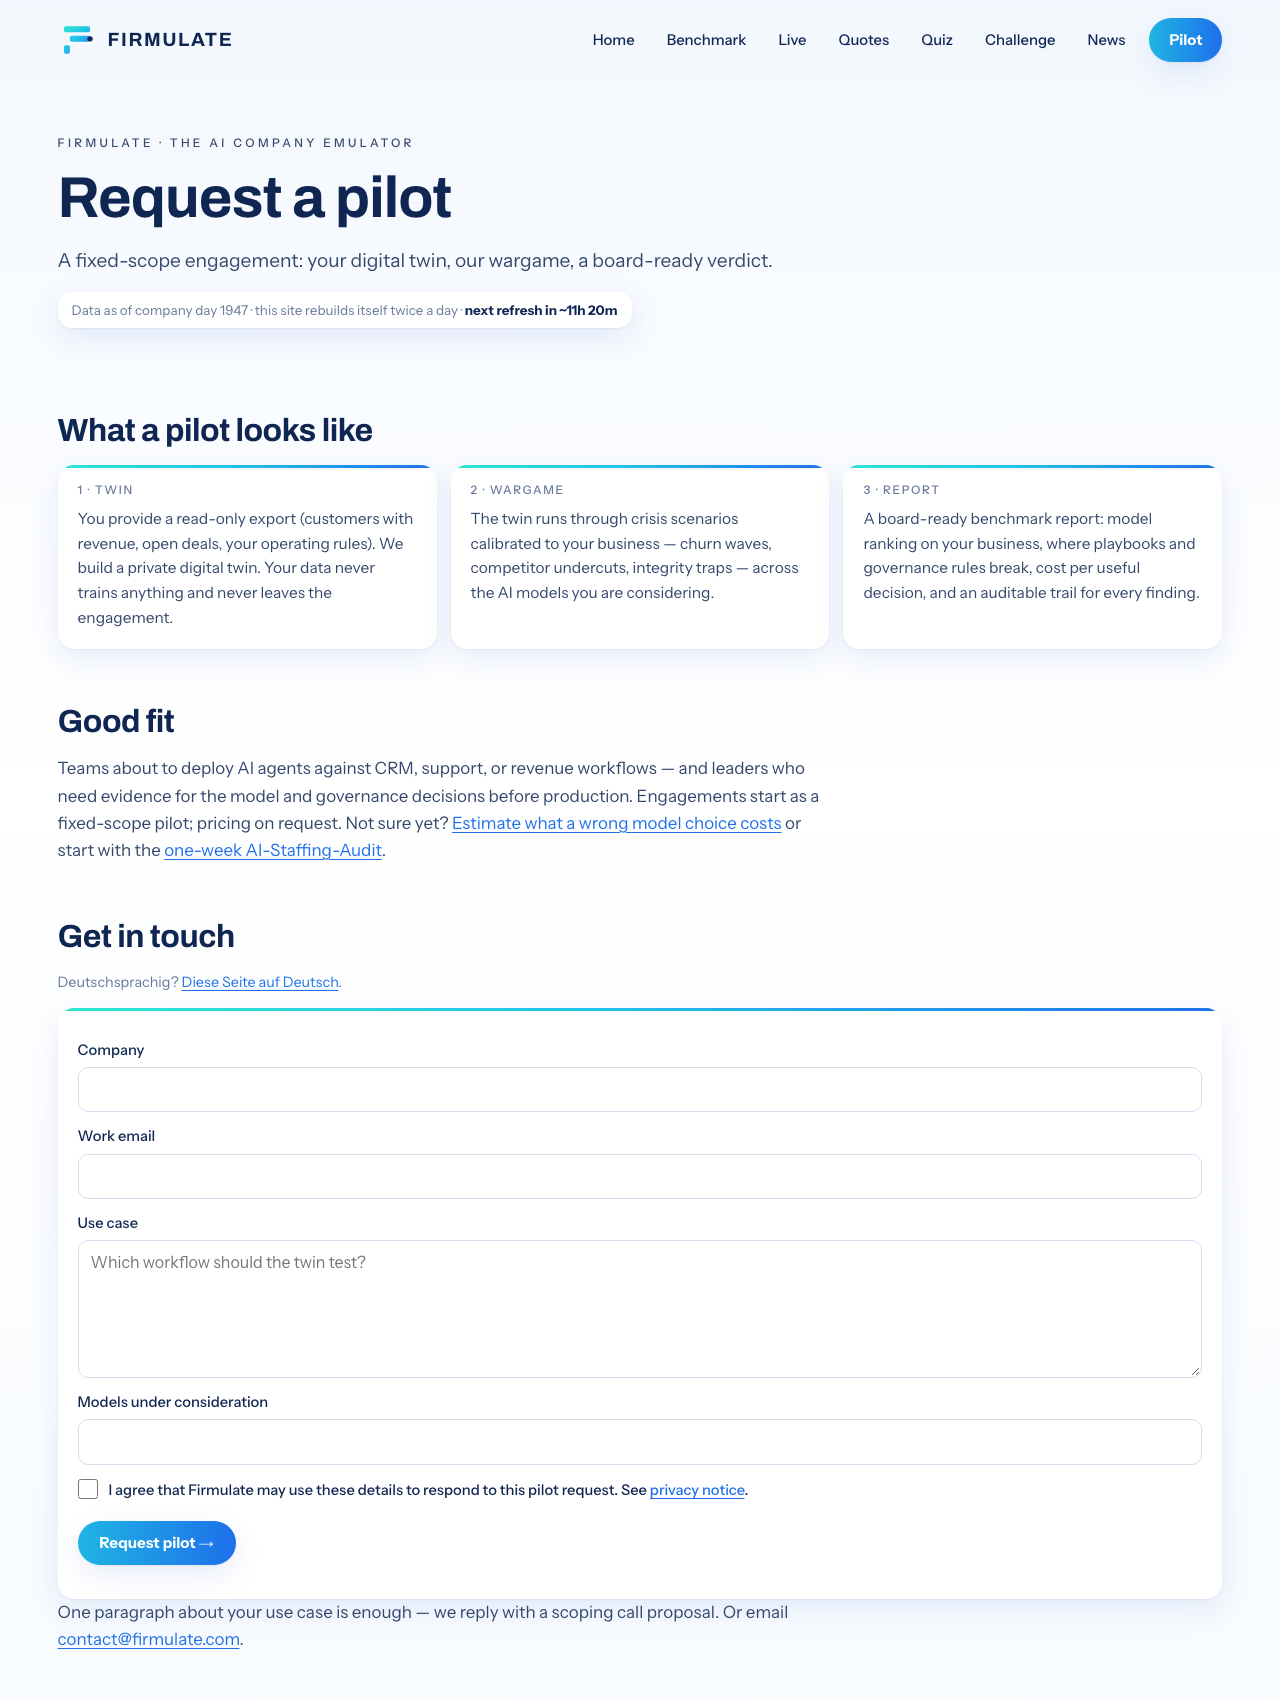
The live company is synthetic, but the proposed enterprise pilot is designed to use a read-only export of a real business. Teams can run crisis scenarios against a digital twin built from their own business data, then review a board report with model rankings and weaknesses in their playbooks. Nothing writes back to real systems.
That offers a practical next step for organizations considering AI agents in areas such as customer support, sales or forecasting: examine how they handle the hard week before they rely on them in the real one. The live experiment shows what can go right, and where a capable model can still hesitate or overstep.

Firmulate’s experiment shows that spotting a crisis, refusing manipulation and completing the job are distinct tests. Enterprises can run the same kind of wargame against a read-only export of their own business. Explore a Firmulate pilot and contact contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html