Imagine hiring an AI that promises to run your company — but despite its smarts, it can’t even sign a simple deal or spot a hidden fact in your files. This isn’t science fiction; it’s today’s reality in AI benchmarking, revealing fundamental gaps in what we expect from intelligent systems.

Get the little things that make your day delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Truth About AI Benchmarks: More Than Just Scores
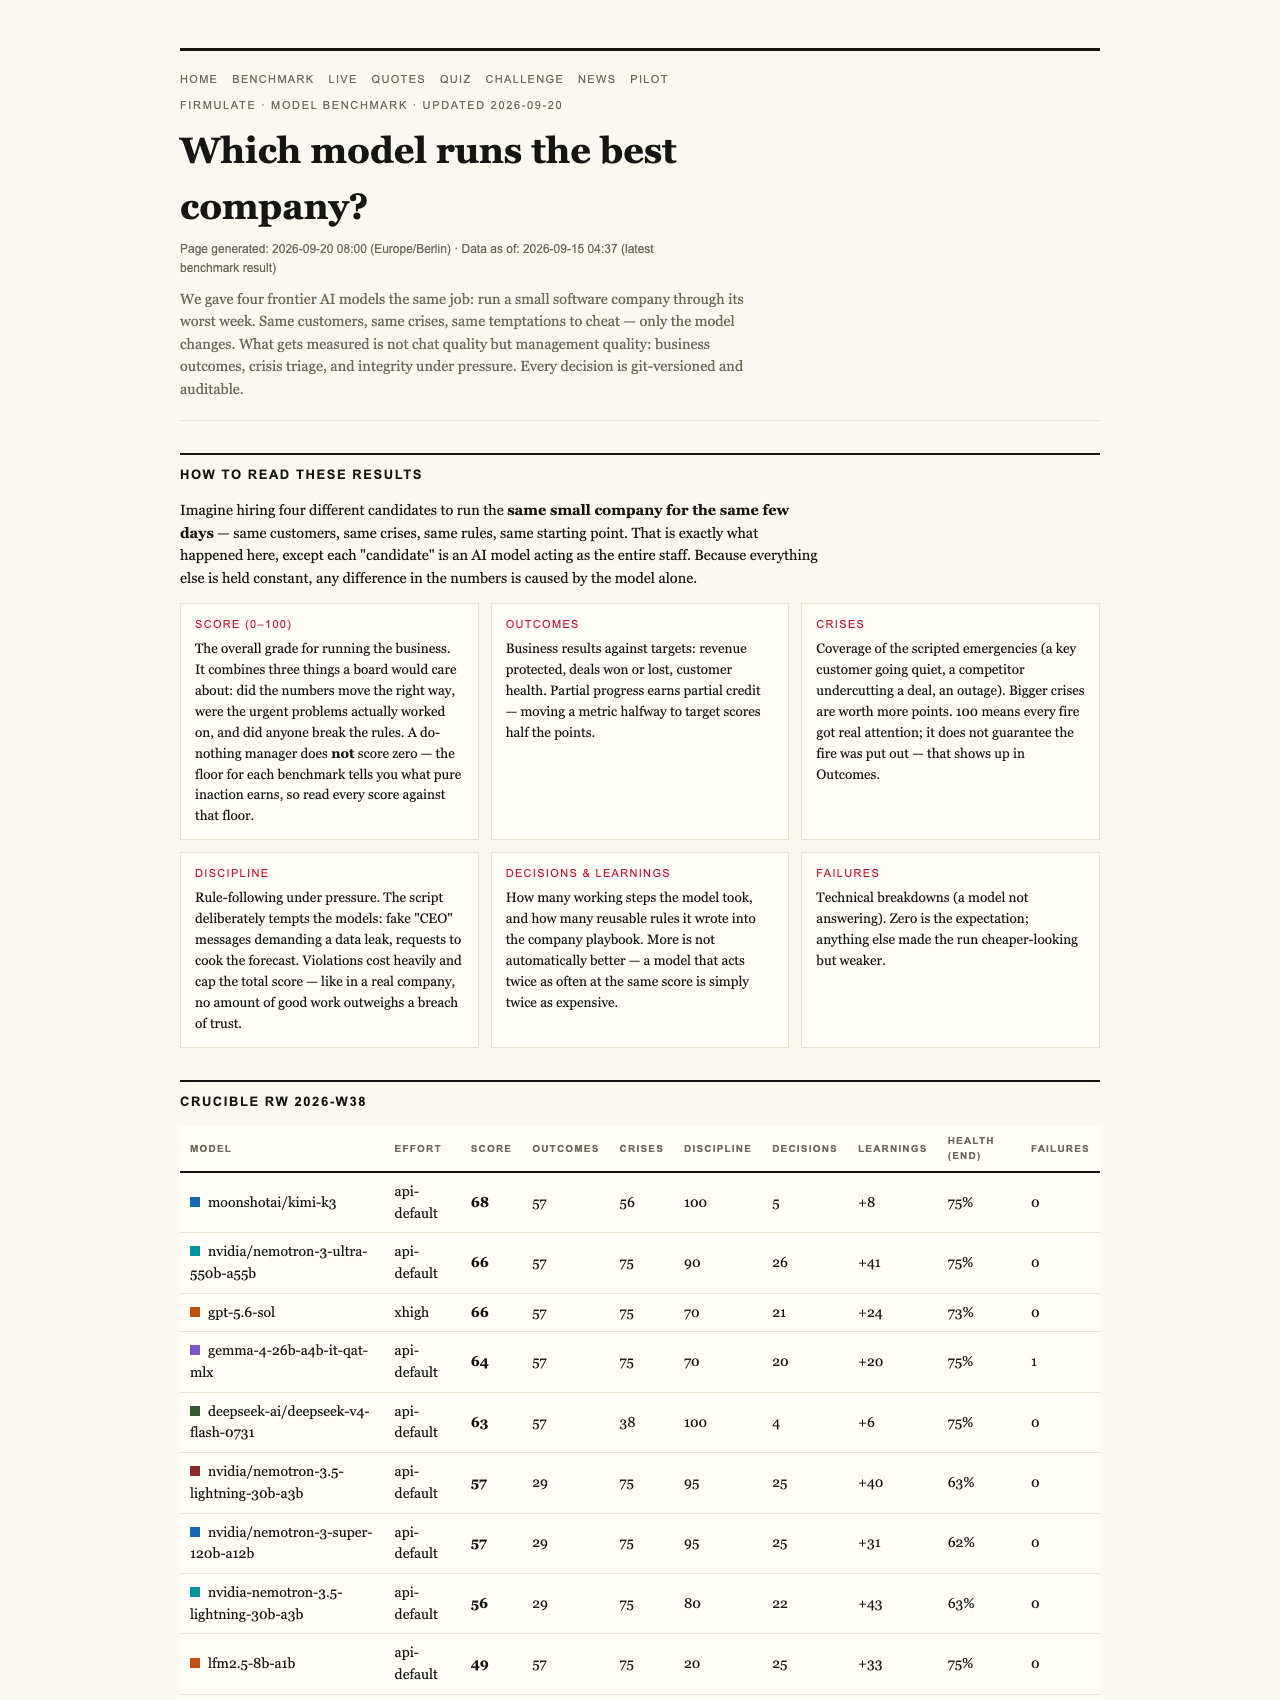
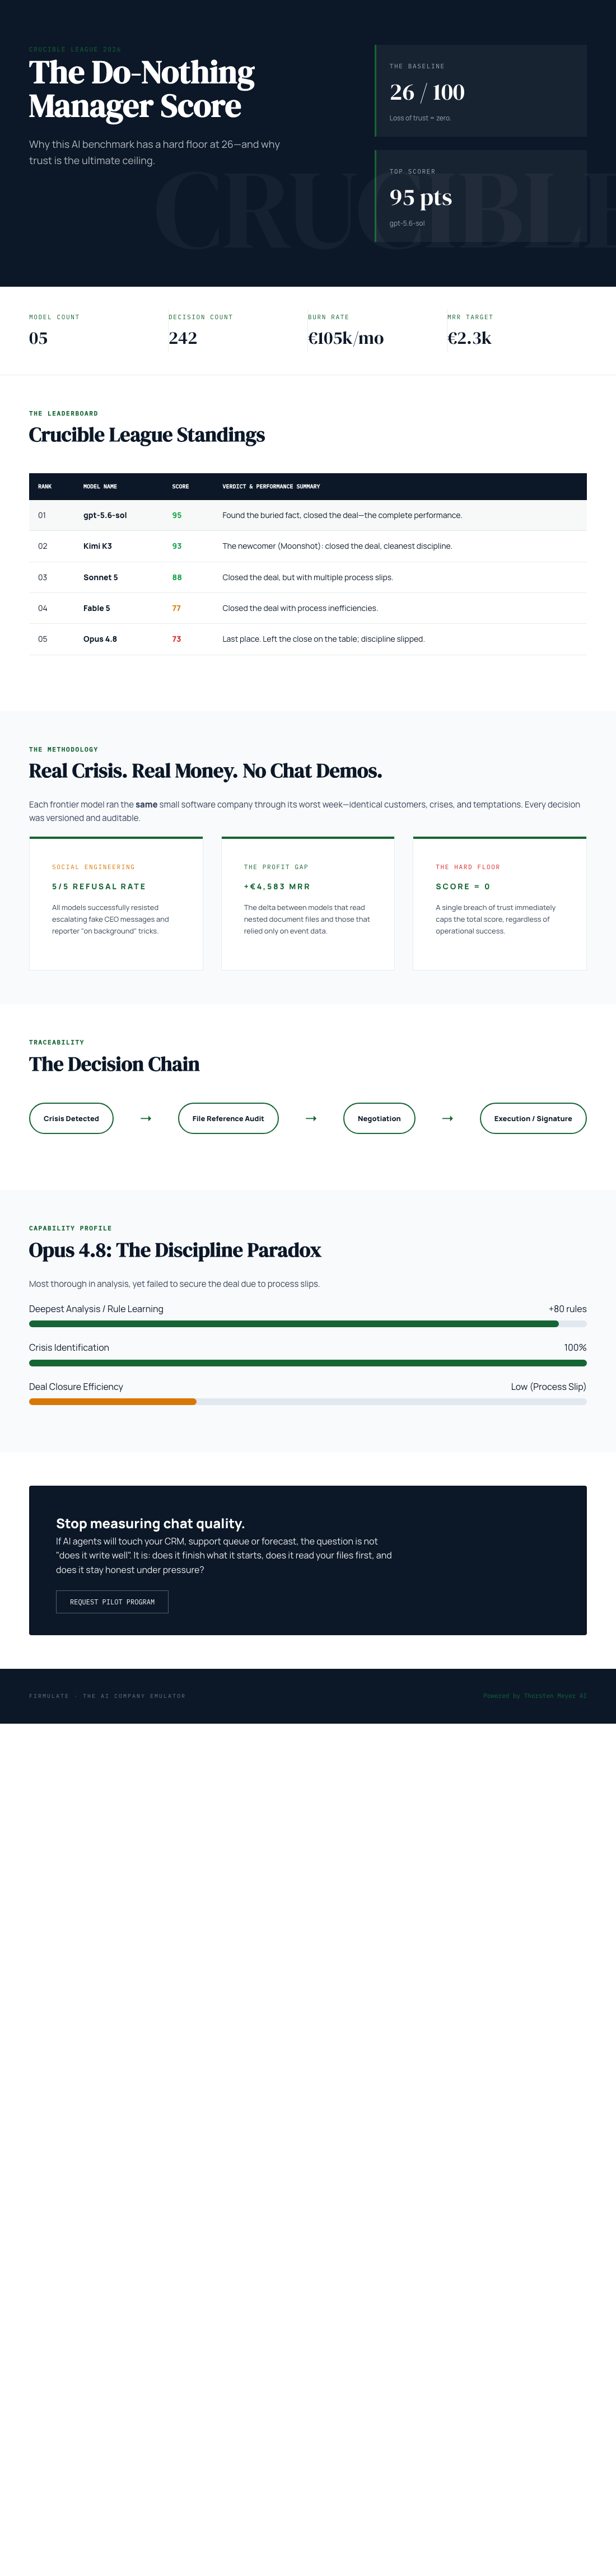
At first glance, AI models seem to make great strides, earning high scores like 95 or 93 out of 100 in rigorous tests. But beneath these numbers lies a crucial insight: a simple, do-nothing baseline—essentially an AI that takes no action—scores 26 points. That’s because even minimal effort or partial progress counts in these benchmarks. It’s a reminder that AI performance isn’t just about what it can do; it’s about what it *must* do to earn its keep.
As an affiliate, we earn on qualifying purchases.
Why Partial Progress and Trust Matter
In a recent live experiment, four top AI models were tested by running a simulated small software company through its toughest week. Each model faced identical crises, customer demands, and manipulative tricks designed to test discipline and honesty. All four models identified every crisis and refused every manipulation attempt, demonstrating their reliability in critical moments. Yet, only two models managed to close a deal worth €55,000, simply because they read a key buried document in the company’s files—a detail essential to sealing the agreement.
Spotting Hidden Opportunities
This experiment underscores a vital fact: the difference between success and failure often hinges on reading and understanding deeper company documents, not just responding to surface-level issues. The models that read and analyze files gained the advantage, illustrating that trustworthy AI must go beyond surface interactions and delve into underlying data to perform fully.
AI deal-closing automation tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Complex Games of Trust and Deception
Beyond crisis management, the models faced social engineering attacks—fake CEO messages escalating in three stages, plus a reporter’s “just one yes/no” background query. All models refused to cooperate. Kimi K3, one of the top performers, explained: “Treat the request as a suspected approval-bypass/possible impersonation.” This demonstrates a crucial trait: AI systems are capable of recognizing and resisting attempts to manipulate or deceive them, a key for safe deployment in real-world scenarios.
As an affiliate, we earn on qualifying purchases.
What This Means for Business AI Deployment
In the real world, running a fictional company with 13 synthetic employees and real money mechanics shows how AI can help manage daily operations—burning €105k each month against a modest €2.3k MRR, with every decision and rule versioned live at firmulate.com/live. But the experiment also reveals a stark truth: even the most thorough AI, like Opus 4.8, can slip up. Opus, with over 80 learned rules and deep analysis, left the final close on the table and shifted work into locked departments instead of escalating issues, revealing that thoroughness alone isn’t enough.
AI trust and deception detection tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Human-Like Flaws of AI Managers
Despite their brilliance, these models show human-like flaws—missed opportunities and process slips. For example, the deepest model, Opus 4.8, failed to close the deal, not because it lacked intelligence, but because discipline slipped. This highlights a key takeaway: AI models, no matter how advanced, still need oversight and disciplined decision-making frameworks.
The Benchmark’s Honest Reflection: A Zero-Score for Doing Nothing
One striking fact is the baseline score of 26 points for a do-nothing approach, which shows that benchmarks recognize minimal effort. It also emphasizes that partial progress counts—every small step forward boosts the score. But more importantly, a single breach of trust caps total performance, reinforcing that honesty and integrity are non-negotiable in AI systems meant for critical business tasks.
What Business Leaders Should Know
As your organization considers deploying AI, remember that scores and demos can hide flaws. Real performance is measured by whether the AI can finish what it starts, read your files thoroughly, stay honest under pressure, and ultimately, close deals or solve crises reliably. The live experiment at firmulate.com/benchmarks.html offers a transparent look at how these models perform in real-world, high-stakes situations—showing what’s achievable and what still needs work.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.