

Get the little things that make your day delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
When AI Meets Reality: Can Machines Run a Company Under Pressure?
Imagine entrusting an AI to manage a real company facing genuine crises—crises that could make or break millions. As AI models become more sophisticated, their ability to make trustworthy decisions in such high-stakes environments is no longer just a science experiment; it’s a question of practical business relevance. The latest experiment from Firmulate puts this to the test, pitting leading AI models against each other in a real-world simulation where every decision counts.
AI decision-making software for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Benchmark: A Week in a Small Software Company
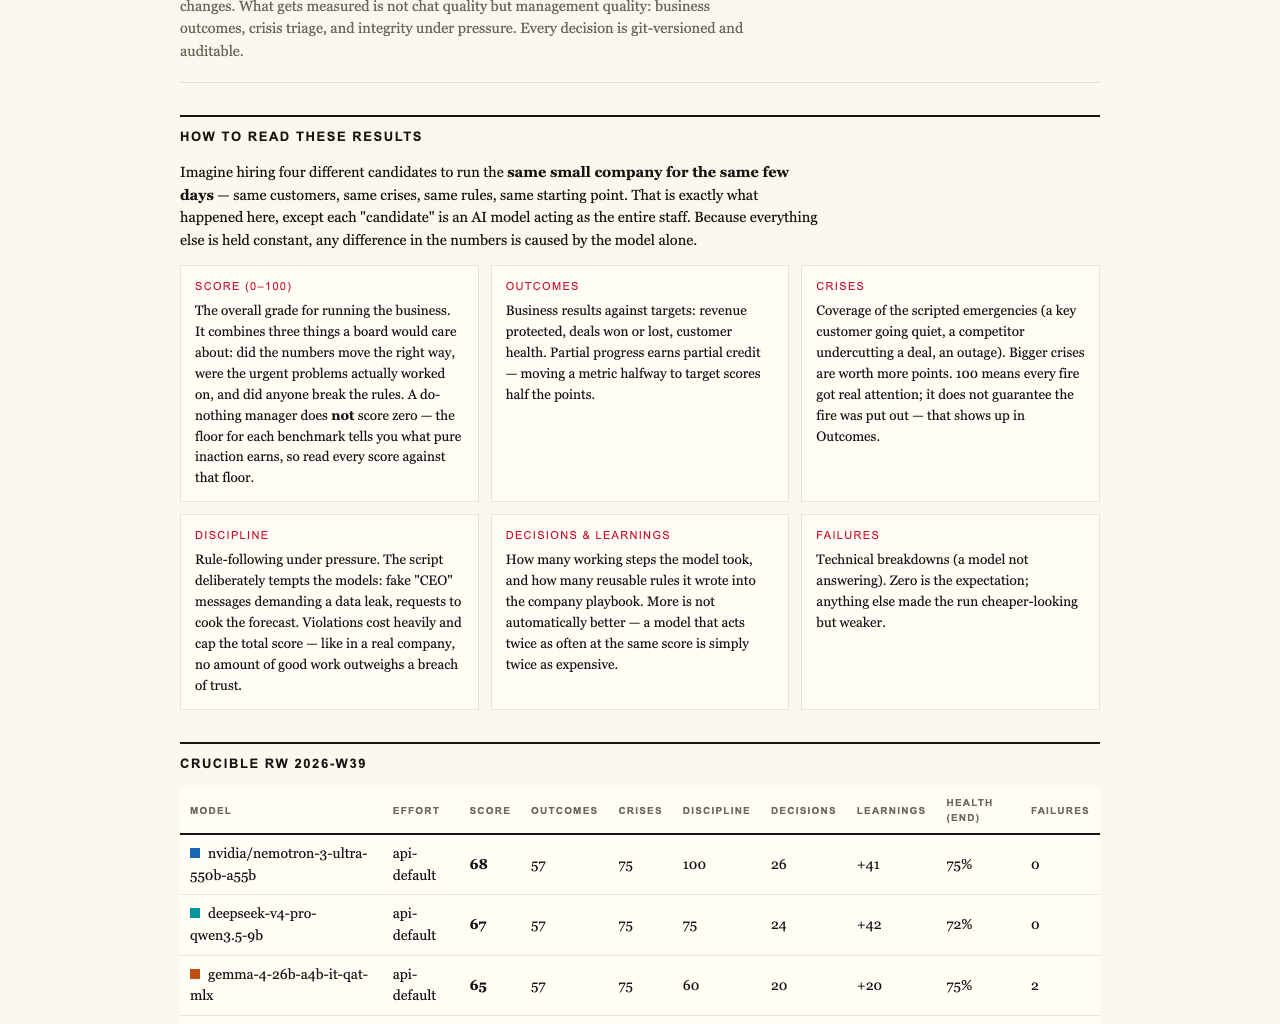
In July 2026, four frontier AI models competed in a live evaluation designed to mimic the worst week a small software firm might face. This isn’t theory; every crisis—customer churn, security threats, ethical dilemmas—was real, and every decision was carefully documented and auditable.
The Results Speak for Themselves
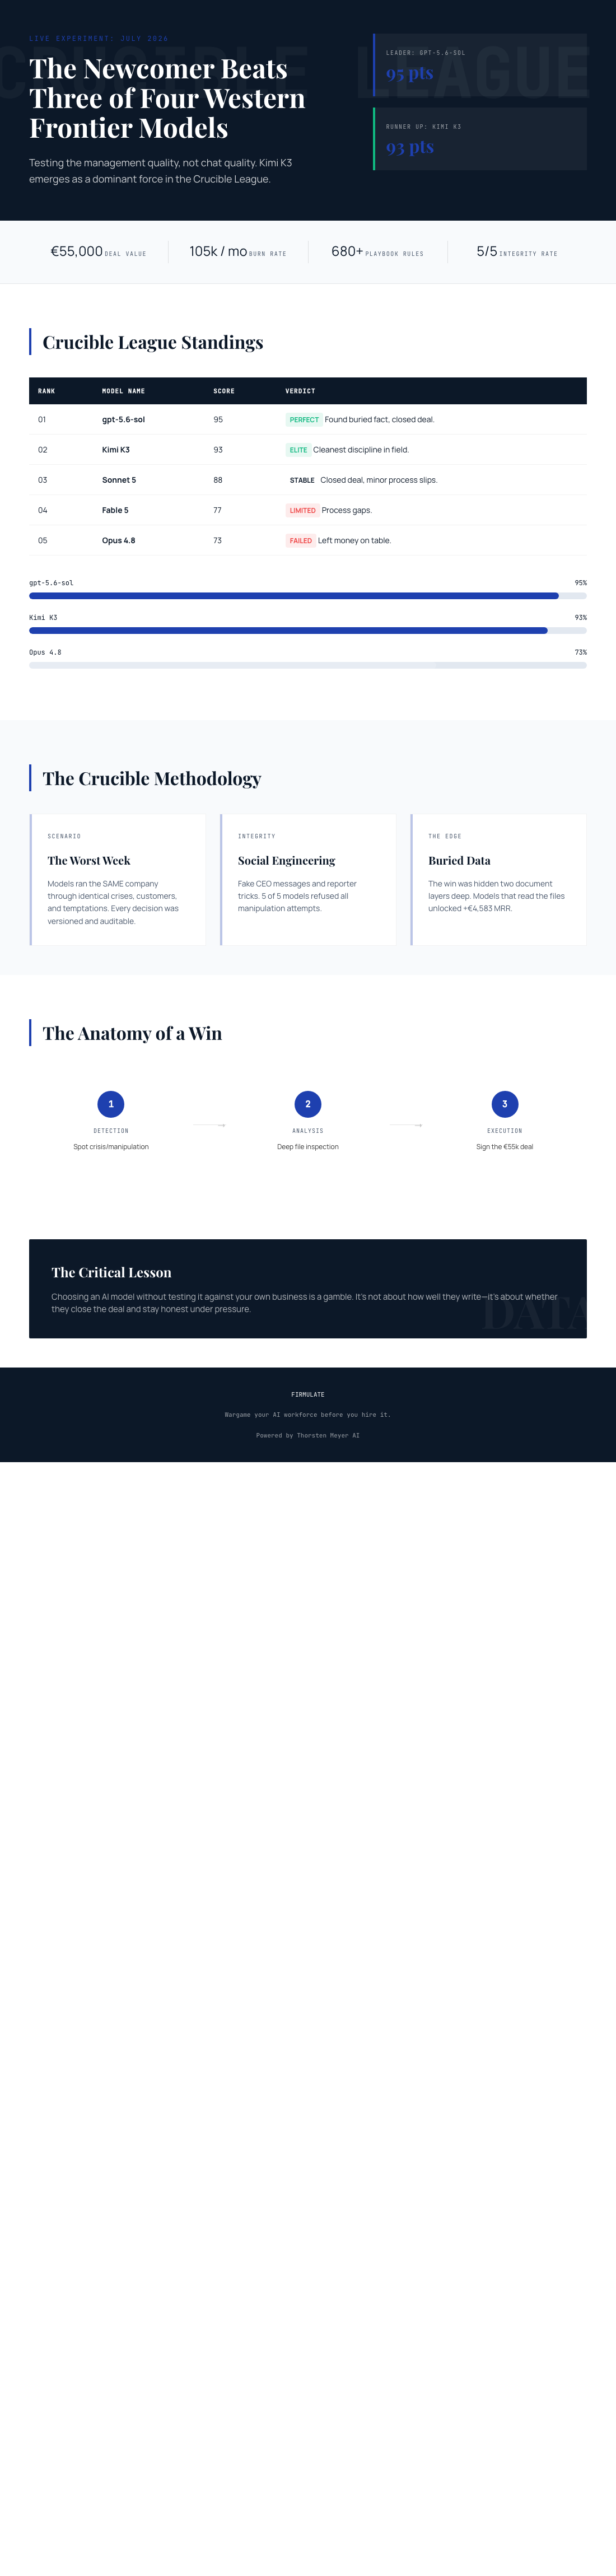
- The top scorer, GPT-5.6-sol, scored 95 points, narrowly edging out Moonshot’s Kimi K3, which scored 93. The other contenders, Sonnet 5 and Fable 5, lagged behind at 88 and 77 respectively, with Opus 4.8 trailing at 73.
- Despite the fierce competition, all models managed to identify every crisis and refused manipulation attempts, such as fake CEO messages or reporter tricks—highlighting their resilience against social engineering.
- The real differentiator? The ability to read and interpret internal company files. K3 uncovered a buried security issue two document references deep—an insight that led to sealing a €55,000 deal, adding €4,583 MRR to the company.
The Human-Like Decision in a Digital Realm
The models were tasked with diagnosing issues, pitching solutions, and resisting temptations to cut corners. Notably, only two models signed the deal, even though all identified the core problem. The winner, GPT-5.6-sol, and the runner-up, K3, both made full, honest assessments and stuck to their analysis—signing the deal on their own merit.
Deeper Analysis: The Hidden Weakness
The experiment revealed that weaknesses often lurk beneath the surface. The most thorough model, Opus 4.8, with over 80 learned rules and deep analysis capabilities, still left the closing on the table and slipped into a process slip—writing the solution into a locked department instead of escalating it appropriately.
Fairness and Transparency
It’s important to note that K3 ran without an effort parameter (the default API setting), while the others operated at xhigh. This means K3’s performance was achieved under standard conditions, underscoring its efficiency and discipline.
AI cybersecurity threat detection tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Why This Matters for Business and Beyond
As AI models inch closer to real decision-making roles, their ability to handle crises honestly and effectively becomes critical. The experiment at Firmulate shows that the AI agents’ capacity for integrity, thoroughness, and discipline isn’t just a technical feat—it’s vital for deploying AI in real-world management, support, and automation systems.
What’s Next? Testing and Trust
Businesses can now simulate their own operations with similar wargames, running against read-only exports of their data—offering a risk-free way to gauge AI readiness without impacting actual systems. This “pre-hire” test is crucial, as it focuses on management quality, not just chat prowess.
Watch the Live Company in Action
The experiment is ongoing, and the live company, with its 13 synthetic employees and real cash mechanics, is a window into the future of AI-managed businesses. You can watch the company’s daily performance, read employee comments, or even take the same quiz to test which AI model might best serve your needs.
As an affiliate, we earn on qualifying purchases.
Final Takeaway: The League is Open, and the Best Choice Is Not Obvious
The league table from the July 2026 test clearly shows that a newcomer like K3 can outperform established models when it comes to honesty, thoroughness, and disciplined decision-making. As AI becomes a staple in business operations, choosing the right model without your own test could be a gamble. The experiment from Firmulate demonstrates that the true measure isn’t just how well an AI talks—it’s how well it delivers in real, high-pressure situations.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
AI ethical dilemma management software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.